Meta Tags Missing From Page Source but Visible in DevTools: Is It an SEO Problem?
We built four controlled pages to test meta tags in HTML, synchronous JavaScript, React useEffect and a delayed API request. See what changes between source and rendered DOM.
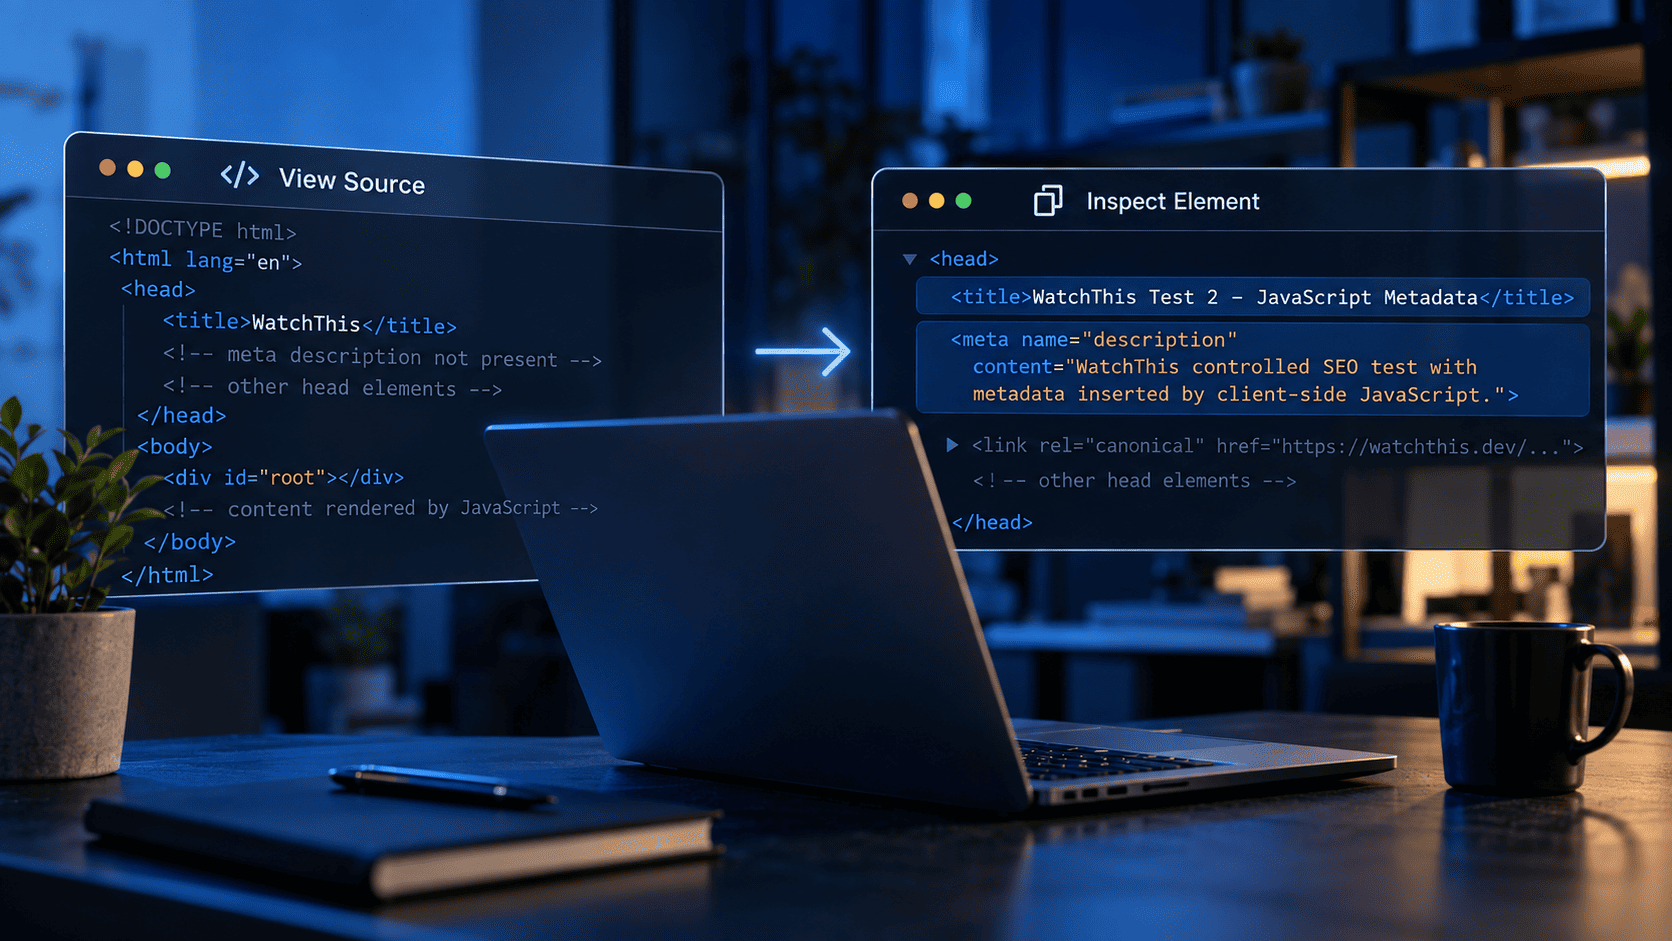
If your title or meta description is missing when you open View Page Source but appears normally in Chrome DevTools, JavaScript is probably creating or changing that metadata after the initial HTML response reaches the browser.
That does not automatically mean Google cannot see the tags. Google explicitly documents that JavaScript can set or change both the <title> element and meta description. The more useful SEO question is how many things must work before those tags exist: are they already present in the server response, created by an immediate script, added after React mounts, or dependent on an API request that finishes later?
To isolate that difference, we created four controlled pages on WatchThis.dev. All four represent the same basic type of page, but each delivers its metadata at a different stage of rendering.
Experiment conducted: September 30, 2026
The short answer
Meta tags missing from page source but visible in Inspect Element are not automatically an SEO problem. They show that the page depends on JavaScript for those tags. Google can render JavaScript and can process JavaScript-generated titles and meta descriptions, so the final metadata may still be available for indexing.
The implementation becomes less robust, however, as more client-side dependencies are added. Metadata already present in the HTTP response is available immediately. Metadata created by synchronous JavaScript requires script execution. Metadata created inside React useEffect additionally depends on the application mounting correctly. Metadata obtained from an API requires the JavaScript application, the request, the API response and the subsequent DOM update to succeed.
The important distinction is therefore not simply HTML versus JavaScript. It is the length and reliability of the path between requesting the URL and the metadata becoming available.
Why View Source and Inspect Element can show different meta tags
View Page Source represents the HTML originally returned for the request. If a server responds with a generic title, an empty application container or no description at all, that is what View Source continues to display. JavaScript executing later does not travel back in time and rewrite the original HTTP response.
Inspect Element shows the browser's current DOM. By the time you inspect the <head>, JavaScript may already have changed document.title, inserted a meta description, modified structured data or rebuilt most of the page.
This is why a developer can look at DevTools and see perfectly valid metadata while an SEO specialist opens View Source and says the same tags are missing. Both observations can be correct because they represent two different moments in the page lifecycle.
We previously examined this distinction more broadly in our raw HTML vs rendered DOM experiment. This test narrows the question down to metadata specifically.
How WatchThis compares the two states
WatchThis is designed around exactly this distinction. It first requests the public URL and records the initial HTML response. It then opens the page in Chromium, allows JavaScript to execute, waits for the DOM to settle and extracts the same SEO elements again.
The comparison includes the page title, meta description, canonical URL, robots directives, H1 headings, internal links, structured data, visible word count and other signals. This means a metadata value that only appears after JavaScript can be separated from a value that was already present before rendering.
You can read the full process in the WatchThis methodology and the technical explanation of how rendering detection works.
Our controlled test setup
Instead of comparing four unrelated websites, we created four pages under the same domain and kept their visible purpose intentionally similar. The meaningful variable is how the title and meta description reach the document.
| Test | URL | Metadata method | Final metadata intended in initial HTML | Final metadata intended after rendering |
|---|---|---|---|---|
| 1 | /tests/meta-html/ | Server / initial HTML | Yes | Yes |
| 2 | /tests/meta-sync-js/ | Synchronous JavaScript | No | Yes |
| 3 | /tests/meta-react-effect/ | React useEffect | No | Yes |
| 4 | /tests/meta-api-delay/ | API request + client JS + 2-second delay | No | Yes |
The complete test directory is also publicly available at WatchThis JavaScript SEO Test Pages, which means the experiment can be reproduced rather than relying only on screenshots from this article.
Test 1: metadata already exists in the initial HTML
The first page acts as the control. Its title and description are generated as part of the original document rather than being created later by the browser.
<title>WatchThis Test 1 – Metadata in Initial HTML</title>

<meta
  name="description"
  content="WatchThis controlled SEO test with title and meta description delivered directly in the initial HTML response."
>
The live test is available at /tests/meta-html/. Because the metadata is already part of the page response, JavaScript is not required to establish the page's final title or description.
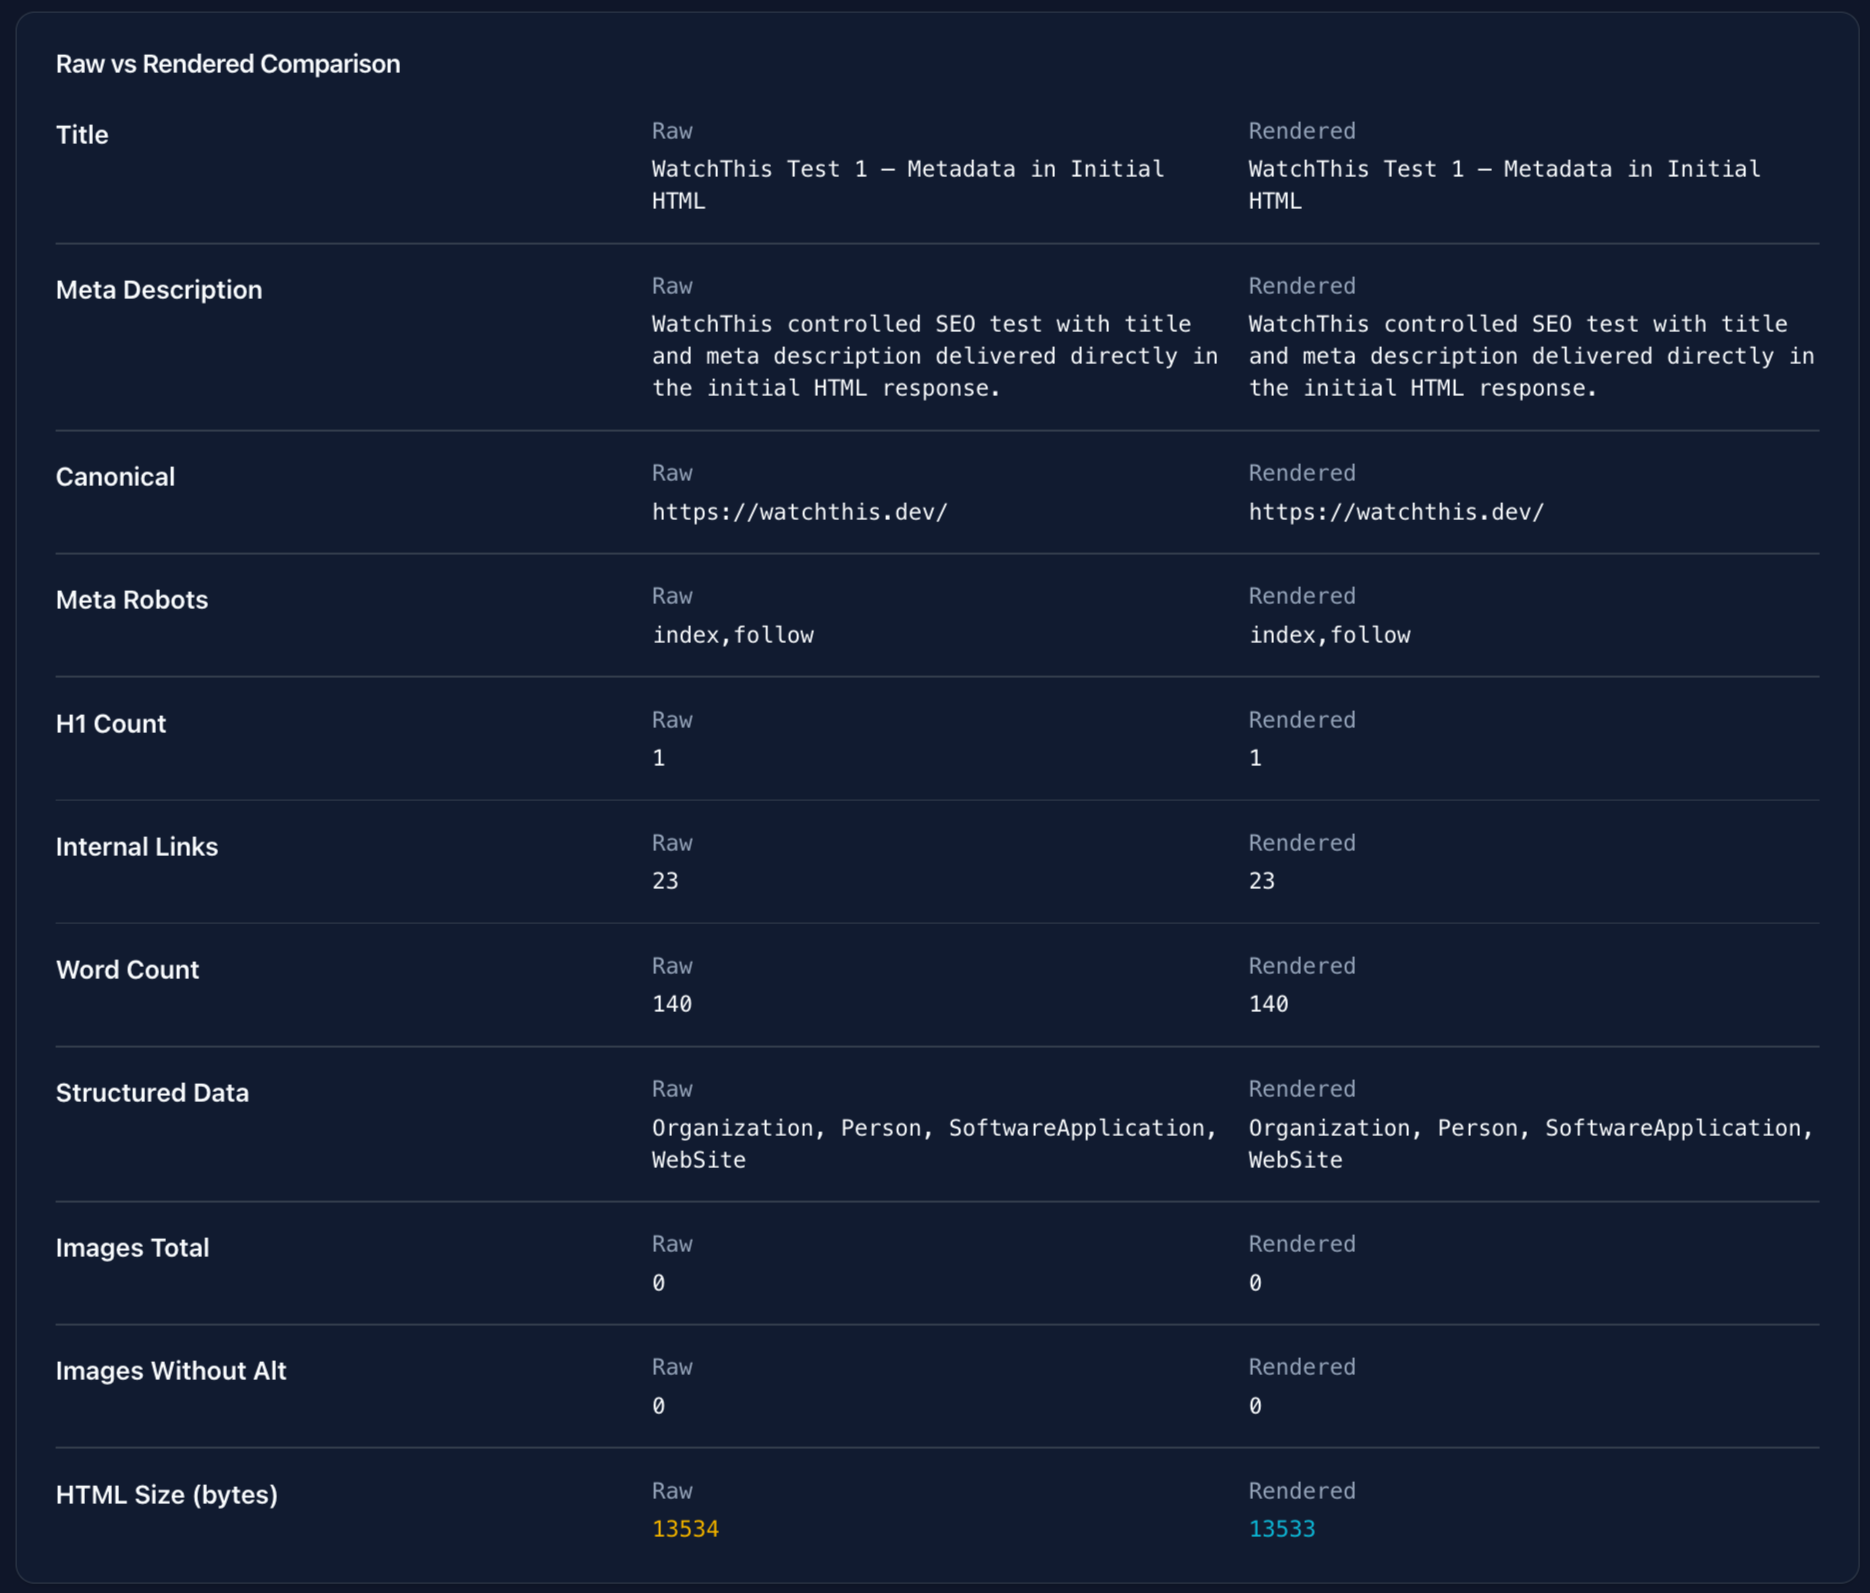
This is the shortest delivery path in the experiment. A crawler does not have to initialize a framework, execute a component lifecycle or wait for another network request before it can identify the page.
Test 2: metadata created by synchronous JavaScript
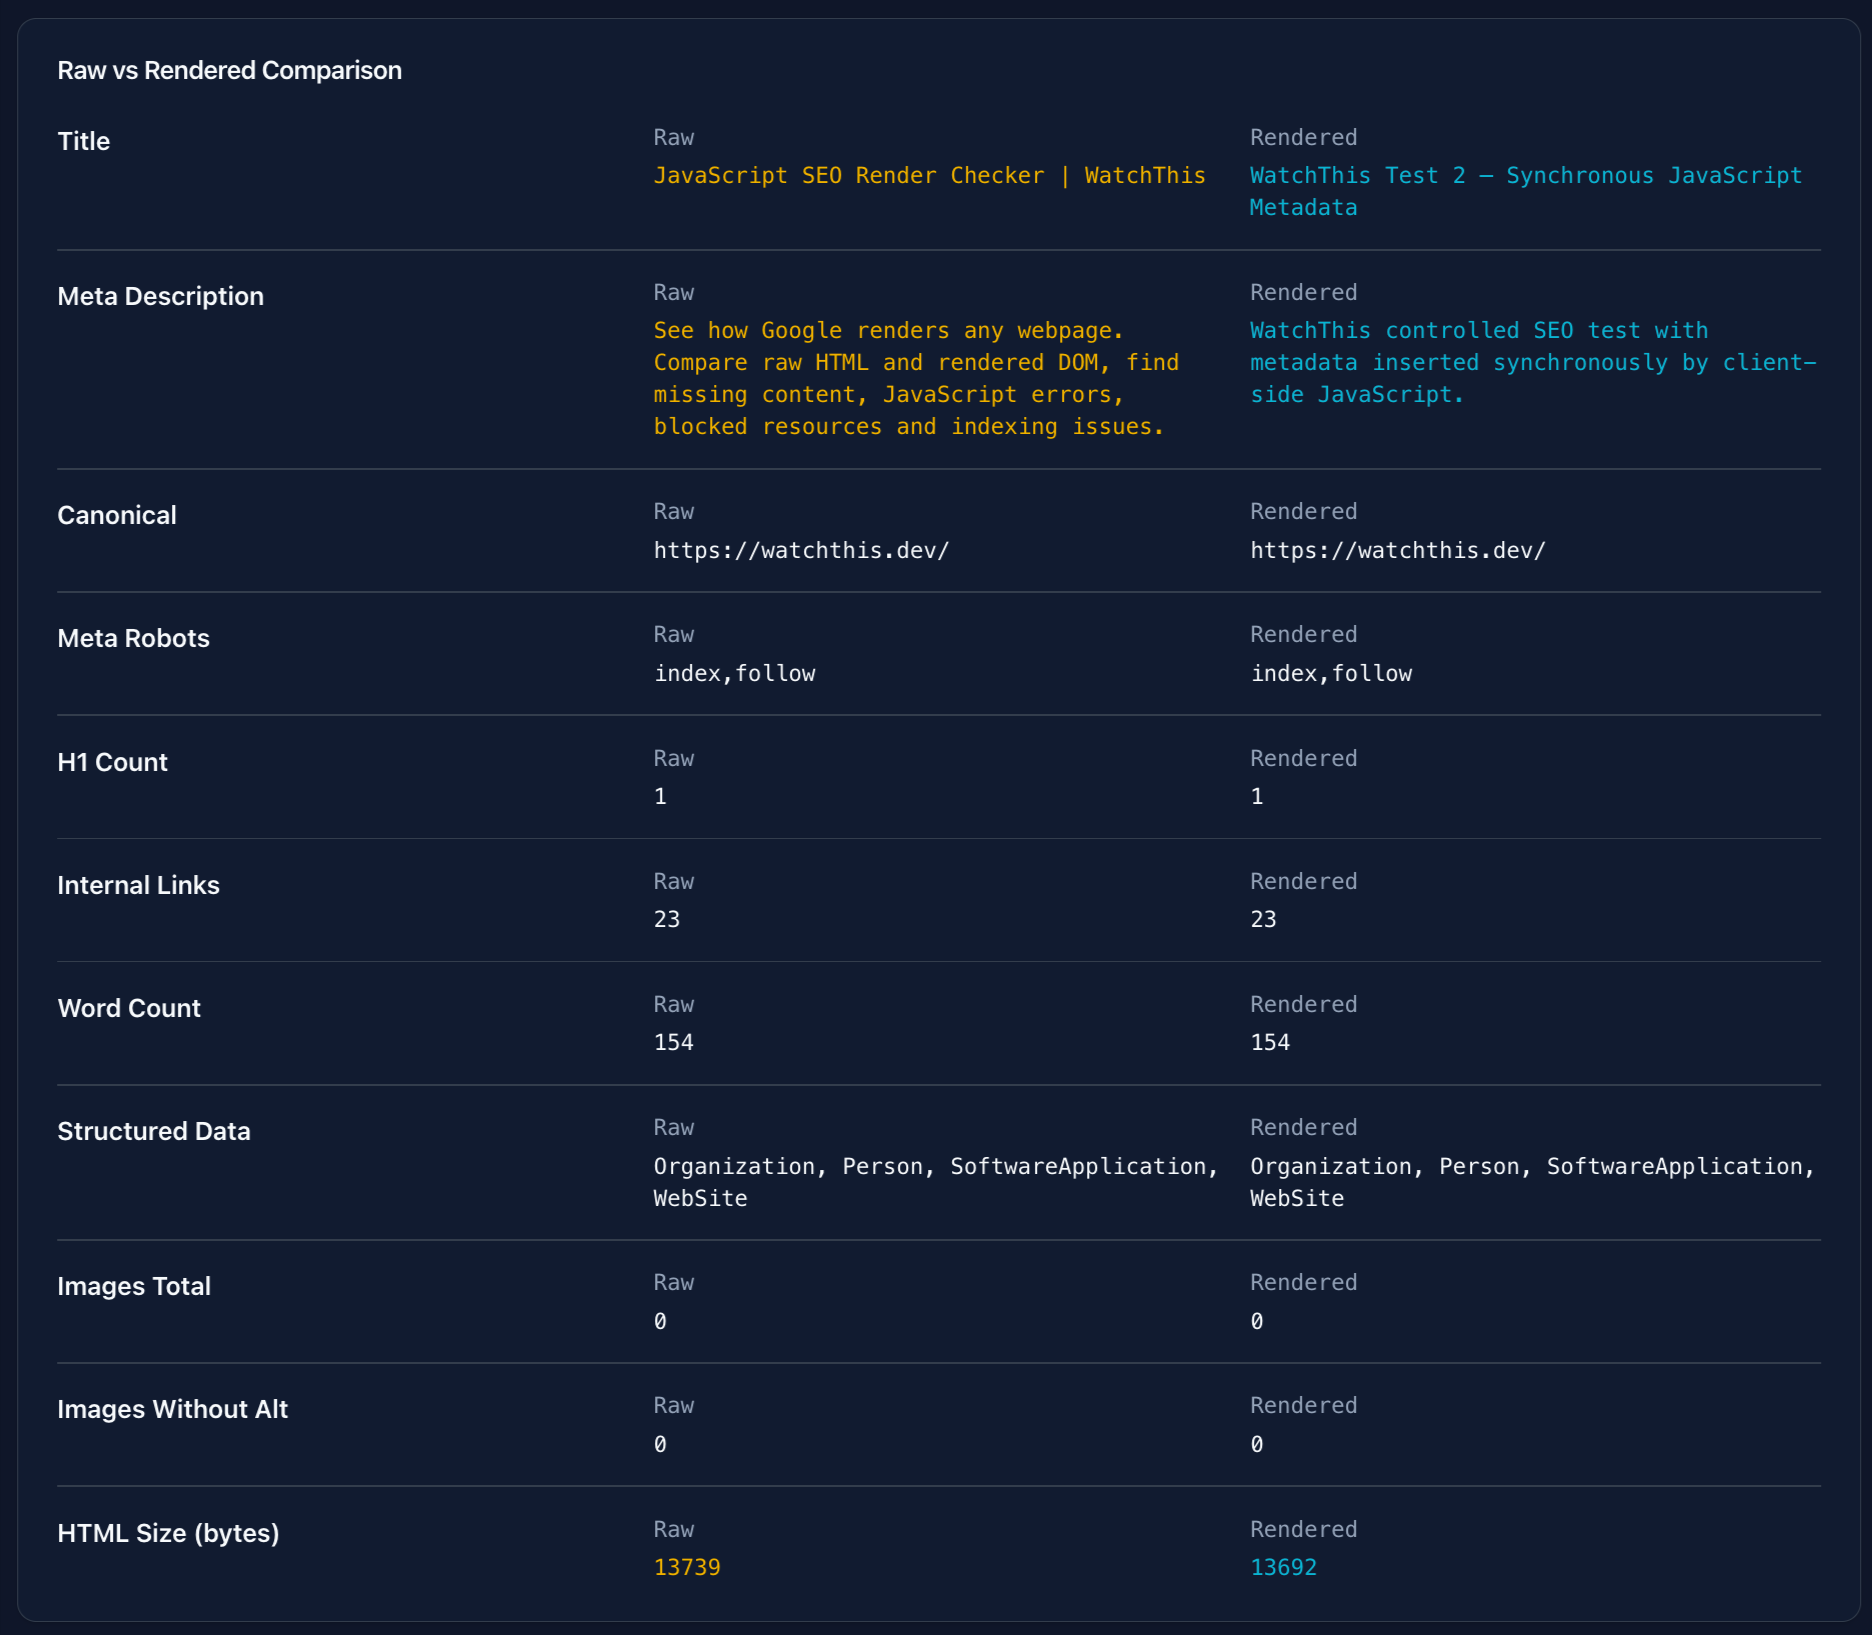
The second page removes the final test-specific metadata from the initial server state and creates it with client-side JavaScript.
The live page is available at /tests/meta-sync-js/.
The logic is equivalent to:
document.title =
  'WatchThis Test 2 – Synchronous JavaScript Metadata';

let description =
  document.querySelector('meta[name="description"]');

if (!description) {
  description = document.createElement('meta');
  description.name = 'description';
  document.head.appendChild(description);
}

description.content =
  'WatchThis controlled SEO test with metadata inserted synchronously by client-side JavaScript.';
The distinction from Test 1 is important even though a browser can finish with an almost identical <head>. In Test 1, the metadata is part of the document from the beginning. In Test 2, successful JavaScript execution becomes a prerequisite for reaching the final state.
Test 3: React meta tags created inside useEffect
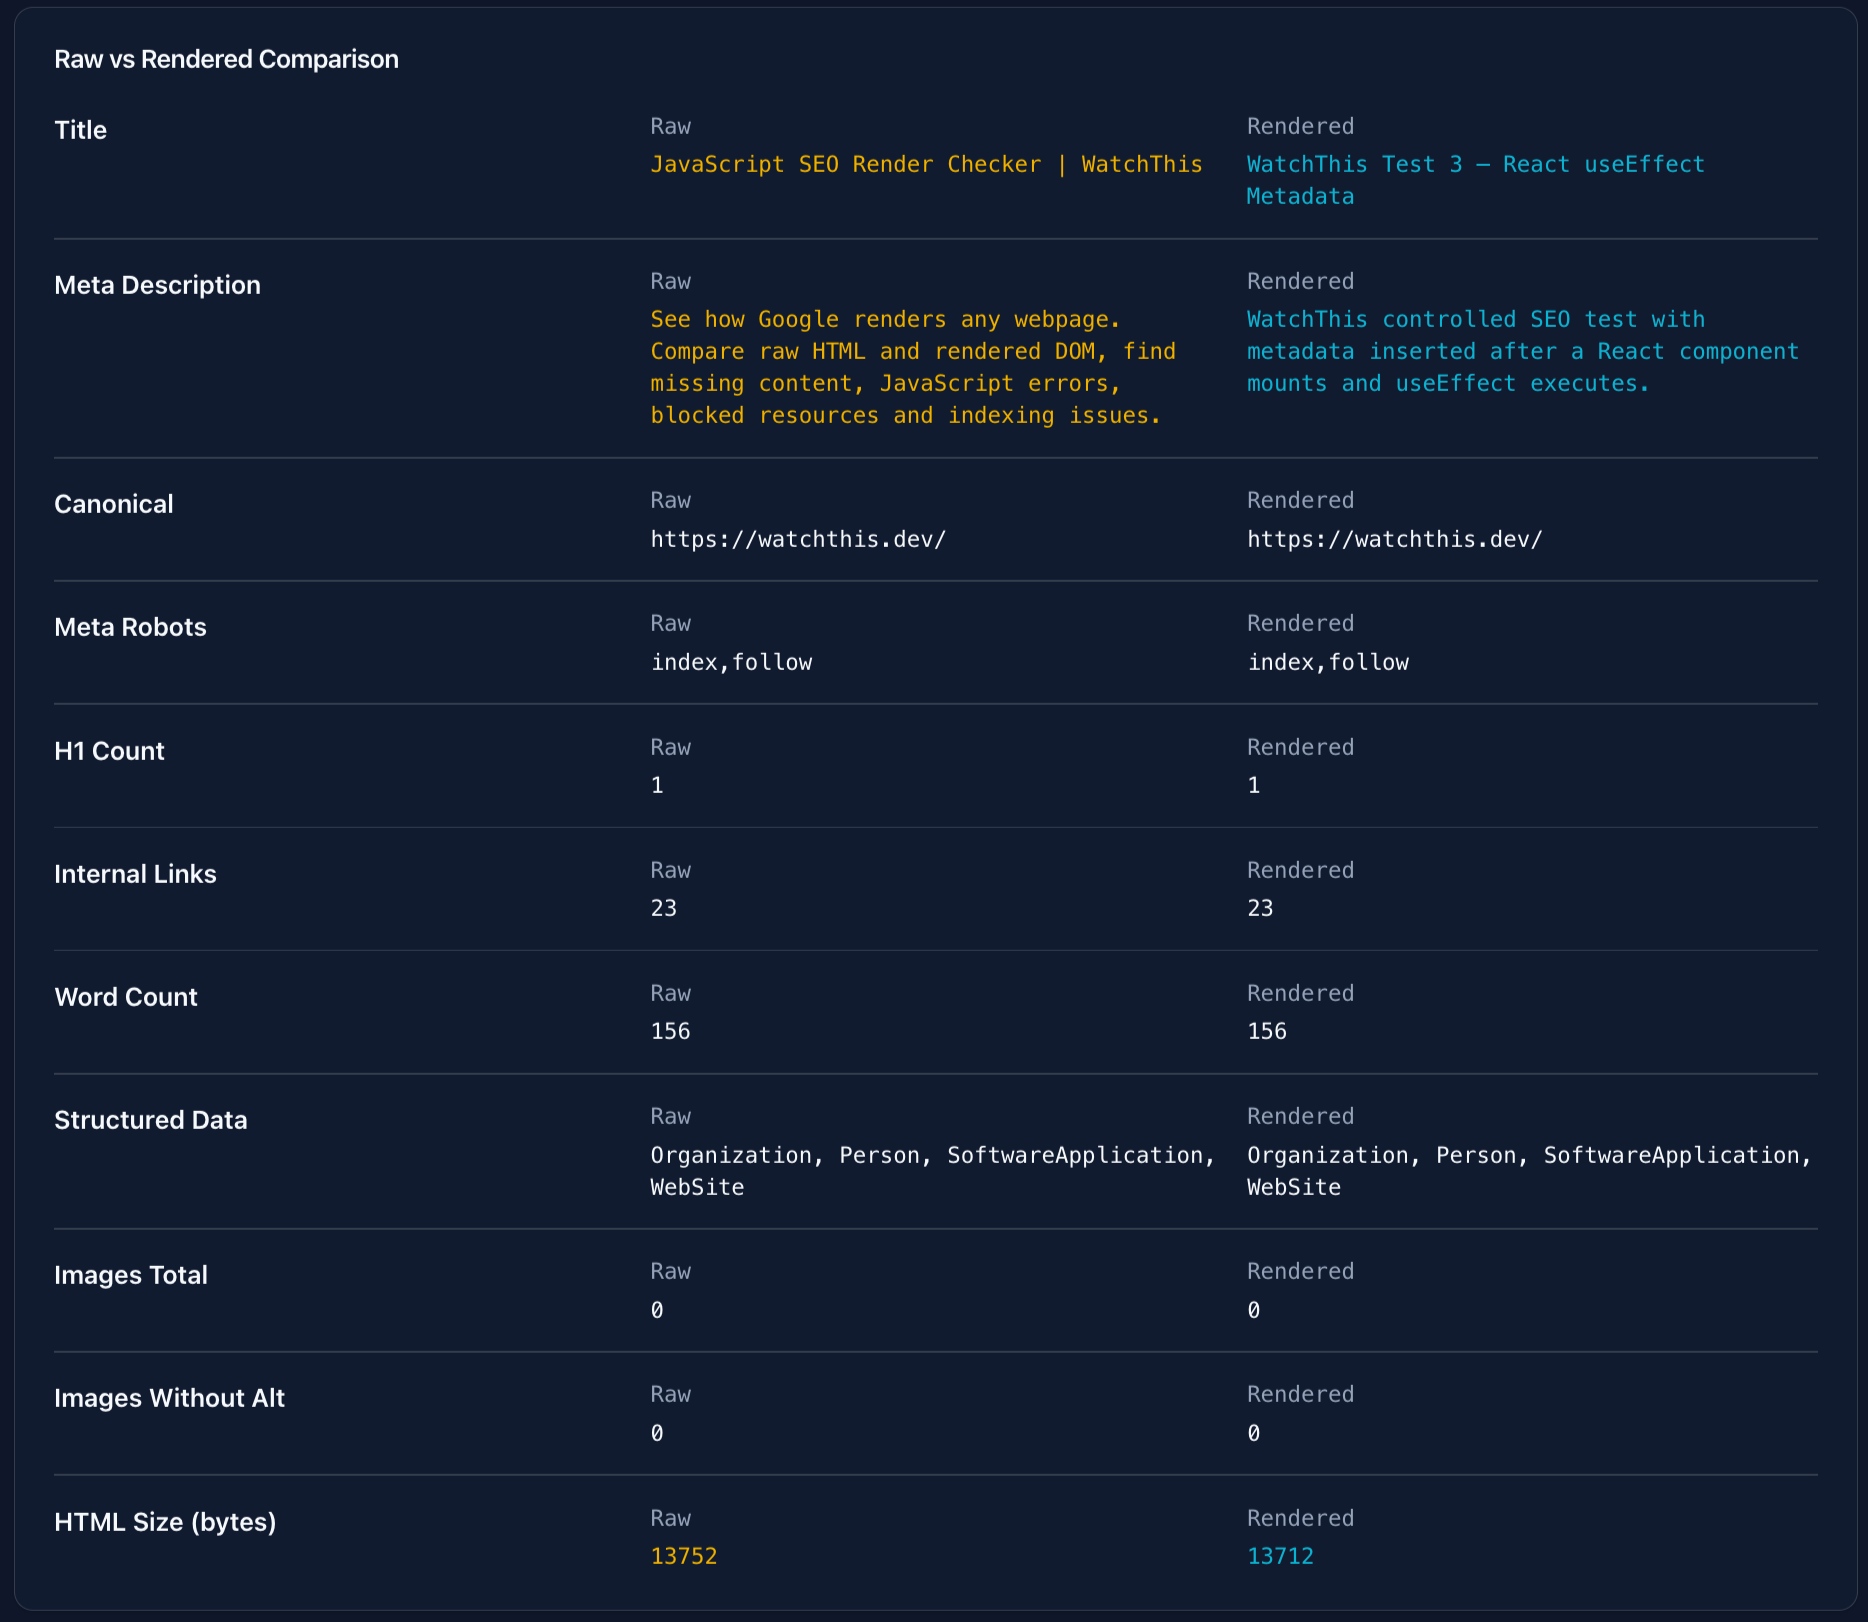
The third page represents a pattern frequently encountered when investigating why React meta tags are not in page source. Instead of executing a small script immediately, the metadata is updated after the React component mounts and its useEffect callback runs.
The live test is available at /tests/meta-react-effect/.
The relevant logic is equivalent to:
useEffect(() => {
  document.title =
    'WatchThis Test 3 – React useEffect Metadata';

  let description =
    document.querySelector('meta[name="description"]');

  if (!description) {
    description = document.createElement('meta');
    description.name = 'description';
    document.head.appendChild(description);
  }

  description.content =
    'WatchThis controlled SEO test with metadata inserted after a React component mounts and useEffect executes.';
}, []);
This adds another step to the metadata delivery chain. The JavaScript bundle must load, React must initialize, the component must mount and the effect must execute. Only then does the document reach the intended metadata state.
That does not mean useEffect metadata is automatically invisible to Google. It means that metadata has become dependent on client rendering even though the framework often has server-side or static metadata mechanisms available for indexable routes.
Test 4: metadata depends on an API request and additional delay
The fourth page intentionally creates the longest dependency chain in the experiment. The final title and description are not supposed to exist immediately. The client application starts, makes an API request, receives the metadata, waits for an intentional two-second delay and only then updates the document.
You can reproduce it at /tests/meta-api-delay/. The page exposes its current state visibly, and after the asynchronous process completes it reports Metadata added to rendered DOM.
The core behavior is equivalent to:
useEffect(() => {
  async function loadMetadata() {
    const response =
      await fetch('/api/test-metadata', {
        cache: 'no-store'
      });

    const data = await response.json();

    await new Promise(resolve =>
      setTimeout(resolve, 2000)
    );

    document.title = data.title;

    let description =
      document.querySelector(
        'meta[name="description"]'
      );

    if (!description) {
      description =
        document.createElement('meta');

      description.name = 'description';
      document.head.appendChild(description);
    }

    description.content =
      data.description;
  }

  loadMetadata();
}, []);
The final DOM can still contain a perfectly normal title and description. The architectural difference is that those two strings now depend on substantially more infrastructure. The application must execute, the request must be allowed, the endpoint must respond correctly, the response must be parsed and the client must remain active long enough to update the DOM.
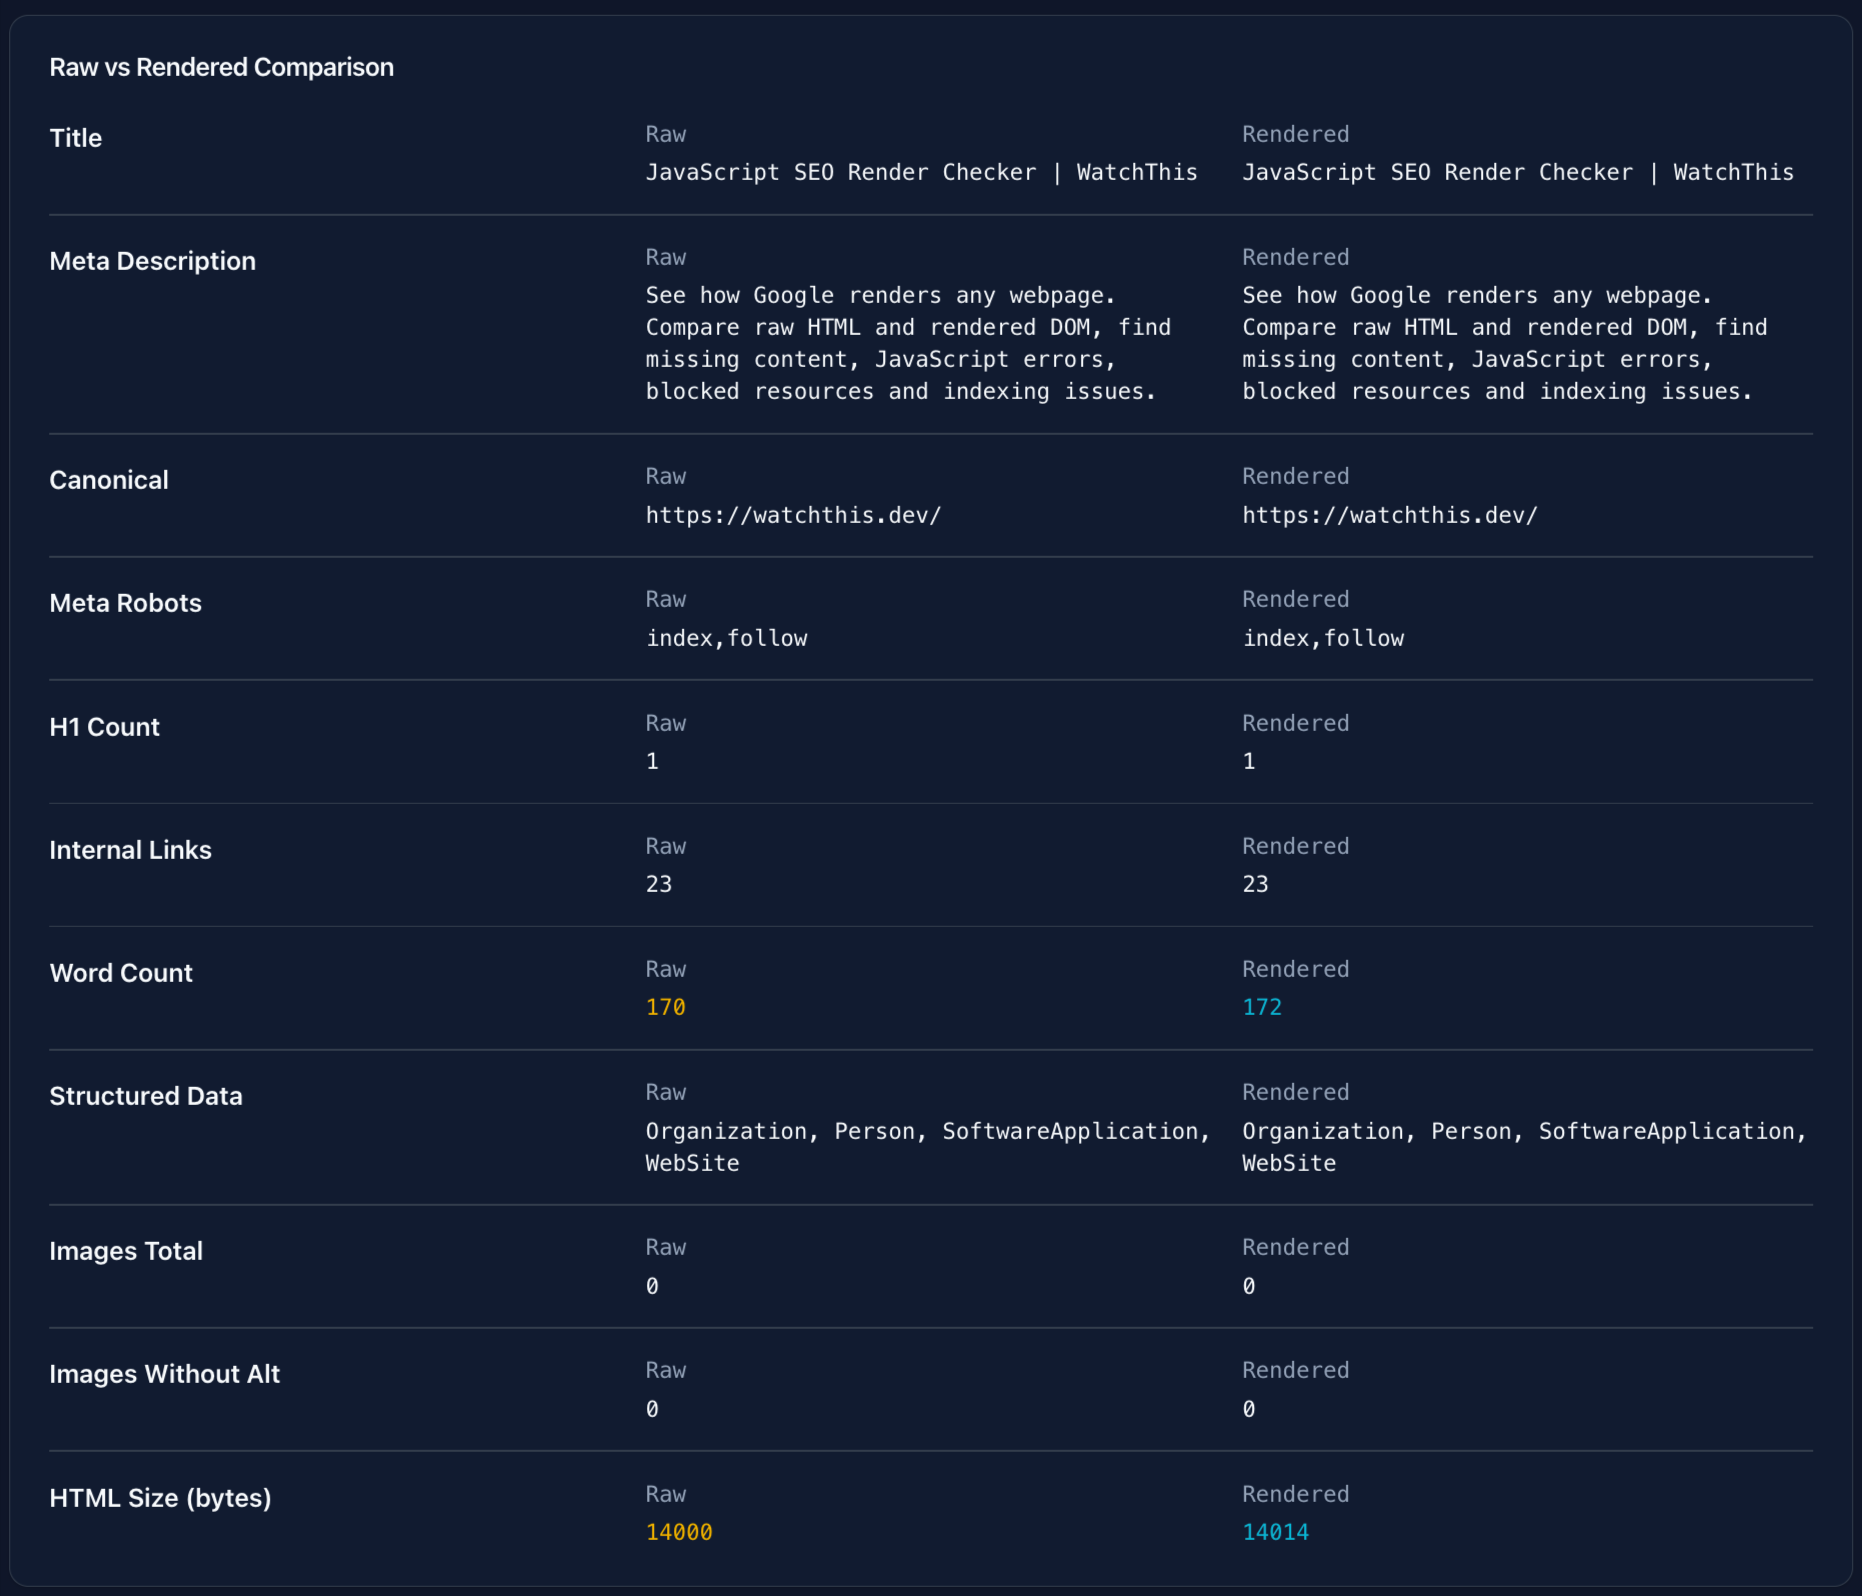
The same final DOM does not mean the same implementation
This is the most useful lesson from the four-page setup. A developer inspecting only the final DOM could potentially see the same kind of title and description on every page. That view alone hides the fact that the four pages reached their metadata through very different paths.
Four pages can end with the same title and meta description while exposing those signals to crawlers at completely different stages of rendering.
Test 1 communicates its metadata in the response itself. Test 2 introduces JavaScript execution. Test 3 introduces the React component lifecycle. Test 4 adds another network request and timing dependency. The end result can look similar while the number of failure points is very different.
What the experiment isolates
The experiment is deliberately not a ranking test. We are not claiming that moving a description from JavaScript into server HTML will produce a specific ranking increase, and we are not measuring how frequently Google fails to render any particular framework.
What these controlled pages isolate is metadata availability. They make it possible to see whether a title or description is available before browser execution or appears only after additional processing.
That distinction is diagnostically useful because a successful browser session does not prove that every crawler, preview generator, social bot, AI crawler or other consumer will execute the same JavaScript under the same conditions.
Can Google see JavaScript-generated meta tags?
Yes. Google's JavaScript SEO documentation explicitly says that JavaScript can be used to set or change both the <title> element and the meta description. Google also describes crawling, rendering and indexing as separate stages and uses a recent version of Chrome to render JavaScript.
This is why the statement “If the tag is missing from View Source, Google cannot see it” is too simplistic.
You can review Google's documentation here: JavaScript SEO basics.
The opposite extreme is also unhelpful. “Google runs JavaScript, so it doesn't matter how metadata is delivered” ignores the dependencies required to reach the rendered state. Rendering can be affected by JavaScript errors, failed requests, blocked resources, timing, bot-specific behavior and application bugs.
Is JavaScript-generated metadata therefore bad for SEO?
No. JavaScript-generated metadata is a delivery method, not an automatic penalty. The practical concern is whether the page needs that client-side dependency in the first place and whether it works consistently for the systems that need to understand the page.
A private web application changing its title when a notification arrives has little reason to server-render every title state. A public article, category, product or landing page is different because its basic identity is usually already known before the browser starts running application code.
If the server already knows that a URL is an article titled “React SEO Guide,” postponing that information until useEffect runs normally provides little SEO benefit while adding another dependency.
When does missing metadata in page source deserve attention?
A missing description in raw HTML is not equally serious in every situation. I would investigate more aggressively when multiple important SEO elements show the same dependency: title, canonical, robots directives, primary content, internal links or structured data all appearing only after JavaScript.
The issue also deserves more attention when metadata relies on asynchronous APIs, when JavaScript errors occur intermittently, when requests behave differently for bots, when client rendering produces different URLs or canonicals, or when Search Console's rendered page differs from the browser state seen by users.
One isolated meta description generated reliably in JavaScript is a different situation from an entire public page whose identity cannot be established until several API calls succeed.
Why the API test matters
The API version makes an otherwise invisible architectural difference easy to understand. The final metadata itself may not look unusual. The weakness is the chain behind it.
- The initial HTML must load.
- The JavaScript bundle must load.
- The application must initialize.
- The component must execute.
- The API request must be allowed.
- The API must return successfully.
- The response must contain valid metadata.
- The application must update the DOM.
If the exact same title could have been generated before the response left the server, every extra step exists primarily because of the chosen architecture rather than because the metadata fundamentally requires client-side computation.
What should React sites do?
For public indexable React pages, the practical default is to generate stable page metadata as part of server rendering or static generation whenever the framework supports it. Modern React frameworks provide route-level and server-side metadata systems specifically so important information does not have to wait for useEffect.
This does not make document.title or client-side metadata APIs inherently wrong. They are useful for dashboards, application states, editors, notifications and interfaces whose title genuinely changes as a user interacts with the application.
The key question is whether the metadata describes a persistent indexable URL or a temporary browser state. Persistent URL metadata normally belongs as close to the initial document generation as the architecture reasonably allows.
What about canonical tags?
Canonical URLs deserve even more caution than descriptions. Google states that JavaScript can set a canonical but recommends making canonical information as clear as possible, preferably in the HTML. If an HTML canonical already exists, JavaScript should not change it to a different URL.
Google's current canonical guidance is available in its canonicalization documentation.
We intentionally kept canonical behavior outside the four-test variable because mixing title, description and canonical experiments together would make the results harder to interpret.
Do not “fix” the issue by creating conflicting metadata
Once a team discovers that metadata is missing from source HTML, an easy mistake is to add a second server-side version without removing or coordinating the JavaScript version. The raw response can then contain one title or description while the rendered DOM contains another.
That can be harder to debug than having the metadata only in one place because different systems may encounter different values. If metadata exists in both states, stable SEO-critical values should normally remain consistent unless there is a deliberate reason for the client to change them.
How to test your own page
If your meta description is only visible in Inspect Element, do not start by assuming the page is broken. Compare the two document states first.
- Open View Page Source and search for the final
<title>and<meta name="description">. - Open DevTools and inspect the current
<head>. - Run the public URL through the WatchThis JavaScript SEO checker.
- Compare the raw and rendered title, description, canonical, H1, links and structured data.
- Check JavaScript errors and failed requests if important elements appear only after rendering.
- For important indexing decisions, confirm the production URL with Google Search Console URL Inspection.
This workflow separates two different questions: Does the browser eventually create the right metadata? and Was that metadata available before JavaScript was required?
Reproduce the experiment yourself
All four controlled pages remain publicly accessible:
- Test 1 — Metadata in Initial HTML
- Test 2 — Synchronous JavaScript
- Test 3 — React useEffect
- Test 4 — Delayed API Metadata
You can also open the complete JavaScript Metadata Test Pages index and run each URL independently through WatchThis.
Our practical conclusion
The useful conclusion is not that JavaScript metadata is inherently bad. It is that seeing a tag in DevTools does not tell you how that tag reached the document.
A title delivered in the server response and a title added two seconds later after an API request may eventually look identical inside the browser. From a rendering architecture perspective they are not equivalent: the second version requires more successful steps before the metadata becomes available.
Google can process JavaScript-generated titles and descriptions, which means missing metadata in View Source is not automatic evidence of an SEO failure. At the same time, when stable metadata for an indexable URL is already known on the server, delivering it directly in the initial HTML removes avoidable dependencies.
The most useful diagnostic is therefore not simply “Is JavaScript being used?” It is “Which important SEO signals exist without JavaScript, which appear only after rendering, and what has to succeed before they get there?”
FAQ
Why are my meta tags not showing in page source?
The most common reason is that JavaScript creates or changes them after the initial HTML has already been returned. View Source shows the original response, while DevTools shows the current DOM after JavaScript execution.
Why are my React meta tags not in page source?
If the metadata is created inside client-side code such as useEffect, it does not have to exist in the initial server response. It can appear later after React mounts and the effect executes.
Is a meta description only visible in Inspect Element bad for SEO?
Not automatically. Google can render JavaScript and can process JavaScript-generated meta descriptions. The situation is still worth investigating because the description depends on successful client rendering and not every crawler necessarily processes JavaScript in the same way.
Can Google see meta tags generated by JavaScript?
Yes. Google's JavaScript SEO documentation specifically states that JavaScript may be used to set or change both titles and meta descriptions.
Does Google see exactly what I see in Inspect Element?
No. Inspect Element represents the DOM in your browser session. Google renders the URL in its own environment, where cookies, network requests, permissions, resources and other conditions may differ.
Should title tags be present in raw HTML?
Google can process titles created by JavaScript, but for stable indexable pages, delivering a known title in the initial HTML removes a rendering dependency and makes the signal available immediately.
Should React useEffect be used for SEO metadata?
It can work, but it is usually unnecessary for stable metadata on public indexable pages when the framework provides server-side or static metadata generation. useEffect is more naturally suited to metadata that reflects temporary client application state.
How can I check whether JavaScript changes my metadata?
Compare the initial HTML response with the rendered DOM. WatchThis performs that comparison automatically and reports differences in title, description, canonical, robots directives and other SEO elements.